What is a talk box?
A talk box is an effect that sends the sound of an instrument up a plastic tube into the player’s mouth. The player shapes that sound with the mouth as if speaking, and a microphone in front of the mouth picks up the result, so a guitar or synth seems to sing words. The player’s own voice stays silent.
The talkbox (both spellings are common) is an acoustic effect, not an electronic one. The instrument becomes the vocal cords and the mouth becomes the filter. That one fact explains how it sounds, why it is awkward to play, why it differs from a vocoder and why no plugin can be quite the same thing.
- A talk box is an amplified instrument, a speaker driver, a tube, your mouth and a microphone. The mouth filters the instrument, a normal vocal mic records it.
- A vocoder does the same job electronically, with a bank of band-pass filters. A 16-band vocoder kept 44 to 53% of a vowel’s shape in my model, with the mouth as the 100% reference.
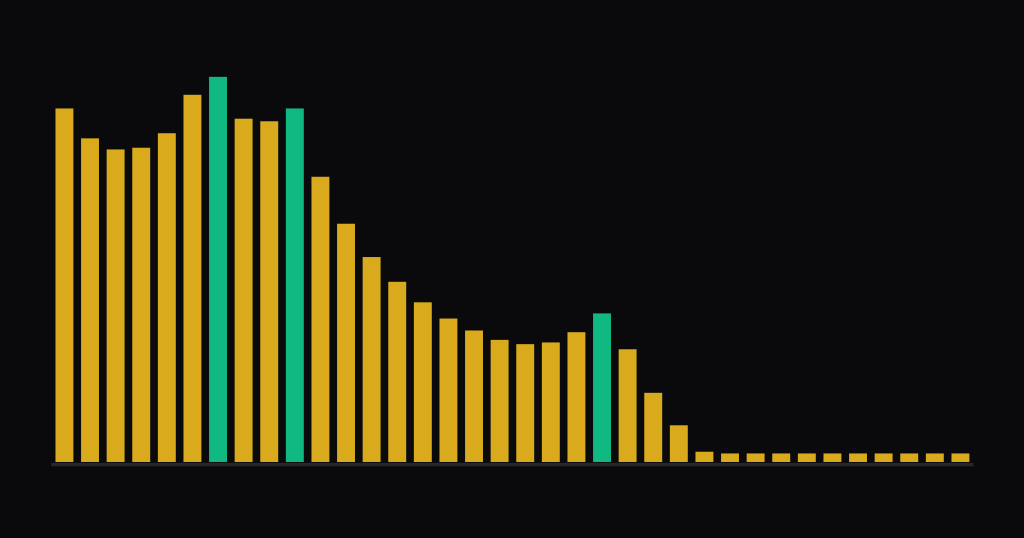
- Lower notes talk better, down to about A2. In my test the vowel envelope error rose from 0.9 dB at A2 to 4.5 dB at A4.
- The idea goes back to the Sonovox of 1939. Bob Heil’s famed box for Joe Walsh and Peter Frampton followed, and Roger Troutman made it a synth sound.
How a talk box works
A talk box chain has five links in a row: an amplified signal, a driver, a tube, your mouth and a microphone. Sound On Sound’s Craig Anderton describes the driver as a “horn-type driver, whose output goes to a short, flexible piece of tubing.” The tube ends in the player’s mouth. From there, “the mouth acts like a mechanical filter for the acoustic signal coming in from the tube” (Sound On Sound, 2003).
Speech works the same way. Your vocal cords make a buzz full of harmonics, and the shape of your throat, tongue and lips boosts some bands of that buzz and damps others. Those boosted bands are called formants, and they are what makes an “ee” different from an “oo”. A talk box swaps the buzz for a guitar or a synth. Attack Magazine puts it simply: “The instrument signal effectively replaces the lungs and vocal cords” (Attack, 2021). If you want the theory behind formants, my entry on formant synthesis covers it, and each formant behaves much like a band-pass filter that your tongue can move.
The signal chain
The classic Heil Talk Box is passive. Dunlop’s HT-1 manual says it “takes the signal from your Amplifier SPEAKER OUTPUT and sends it through the hose”, and its driver is an “8 ohm speaker rated at 100 watts max power or 50 watts RMS” (Dunlop HT-1 manual). Dunlop’s product page lists the HT1 as a legacy product, “NO LONGER IN PRODUCTION” (Dunlop).
Newer boxes bring their own amplifier. The MXR M222 “contains its own amp and speaker driver” and ships with an 18-volt supply, “an 8′ surgical tube and a mic standclip” (Dunlop / MXR). TheTalkStar, built with keyboard players in mind, calls itself “the only self-powered unit designed for synth use”, which is the maker’s claim rather than a test result (TheTalkStar).
Either way the last link is an ordinary vocal microphone. The Electro-Harmonix Golden Throat, Roger Troutman’s box, “physically pumped audio (not an electronic signal) up a tube” into the mouth, “to then be shaped and captured via an external microphone” (Electro-Harmonix). So the mic hears the mouth, plus whatever leaks around it, and you mix that mic like a vocal, with EQ and a compressor.
How you play it
You mouth the words and stay silent. The HT-1 manual is blunt about it: “Do not make any sound with your voice.” It also says “Place the hose in the corner of your mouth”. Consonants come from the lips and tongue cutting the sound on and off, vowels from the shape of the mouth, and the pitch comes from the instrument. You can play chords through it, but the mouth shapes them as one sound, so every note gets the same vowel at the same moment.
Why lower notes talk better: my test
A mouth can only shape harmonics that are there. A sawtooth at A2 (110 Hz) has a harmonic every 110 Hz, so one or two of them fall inside each formant. At A4 (440 Hz) the harmonics sit 440 Hz apart. The first formant of “beet” (270 Hz) and “boot” (300 Hz) then has no harmonic below it at all, because even the fundamental sits higher (formant values from Peterson and Barney, 1952, as tabulated by Princeton’s CS325 course).
To put a number on it, I modelled the mouth as three formant resonators for five vowels and sampled it at the harmonic series of each note, as a sawtooth wave would supply it. Only the spacing of the harmonics matters in this test, not their levels. For each note I joined the tops of the harmonics into an envelope, a simple stand-in for what the ear gets, and measured how far that envelope strays from the mouth’s real response between 150 Hz and 4 kHz.
The result is clear. Up to A2 the median error stays under 1 dB (0.9 dB at A2), so the harmonics trace the vowels almost exactly. It reaches 1.8 dB at A3, 4.5 dB at A4 and 10.5 dB at E5, where whole formants fall between harmonics. A5 scores lower again (6.3 dB), but that is luck: with only a handful of harmonics left, where they happen to land decides the error, and for “beet” it gets worse (14 dB).
From E4 up, “beet” and “boot” have no harmonic below their first formant. In practice that points to the low and middle register: the lower the note, the closer the harmonics sit, and the more of each vowel the mouth can shape. A separate point, which this test doesn’t measure: the harmonics have to be there at all. A pure sine has only one, so there is nothing for the mouth to shape, while classic subtractive sounds with the filter open have plenty.
The limits of the test: the formant bandwidths (80, 100 and 150 Hz) are my assumption, fixed for all vowels, and a joined-up envelope is a simple stand-in for hearing. I reran the test with all bandwidths halved and doubled: A2 came out at 1.5 and 0.4 dB, A4 at 6.0 and 3.4 dB, so the trend holds while the exact decibels depend on the model.
The model also leaves out the driver and the tube, which likely can’t reproduce the deepest lows well, and a tube at the corner of the lips is not quite the same as a voice from the throat. So very low notes won’t do as well in practice as the chart’s E1 and A1 bars suggest.
Vocoder vs talk box
A talk box and a vocoder both make an instrument talk, but they get there in opposite ways. The talk box is acoustic: the real mouth filters the real sound. A vocoder is electronic. In Anderton’s words, “A vocoder has two inputs: one for an instrument (the carrier input)” and one for a voice. Then “the microphone feeds several paralleled filters, each of which covers a narrow frequency band.” The level in each voice band then sets the level of the same band on the instrument (Sound On Sound, 2003).
My entry on the vocoder goes through that design in detail. Attack Magazine puts the mix-up this way: “Often confused with the vocoder, the talk box is an electro-mechanical device”.
| Talk box | Vocoder | |
|---|---|---|
| What shapes the sound | Your mouth, acoustically | A bank of electronic band-pass filters |
| Inputs | One: the instrument, through a driver and tube | Two: a carrier (instrument) and a modulator (voice) |
| Needs a voice signal | No, you mouth the words silently | Yes, sung, spoken or recorded |
| Vowel detail | As sharp as the mouth makes it | Limited by the number and width of bands |
| Typical sound | Wet, throaty, human | Smooth, synthetic, robotic |
| Where it runs | Hardware plus a vocal mic | Hardware, a synth with a vocoder, or a plugin |
How many bands it takes to match a mouth
The practical difference is resolution. A mouth places a formant peak exactly where the tongue puts it. A vocoder can only say “this band is loud”, so the vowel is blurred to the width of its bands. The Korg MS2000 is a good reference point. Sound On Sound counted “two sets of 16 band-pass filters”, called that “a very respectable number in vocoder terms” and gave their centres a range “from 125Hz for channel 1 to 5kHz for channel 16” (Sound On Sound, 2000).
I ran the same five vowels through a modelled vocoder with 8 to 64 bands, each band an 8th-order band-pass filter, with a singing voice at 120 Hz as the modulator and a 110 Hz sawtooth as the carrier. Then I measured how much of the vowel’s shape survived: the peak-to-trough range of the envelope from 200 Hz to 3.3 kHz, with the overall tilt removed, as a share of what the mouth produced.
With 16 bands spread from 100 Hz to 8 kHz, a median 44% of the vowel contrast survived and the second formant landed up to 330 Hz from where the mouth put it. Using the MS2000’s narrower 125 Hz to 5 kHz range, 16 bands kept 53%. It took 64 bands to reach 86%. Smeared vowels are one reason a vocoder sounds smoother and less human than a talk box. Others, such as the carrier being cut off from the voice’s own pitch and breath, aren’t in my model. Neither is better. They are different tools.
The limits of this test: it compares steady vowels only, with no envelope timing and no consonants. The 8th-order slopes and log spacing are my choices, not the MS2000’s measured filters. The mouth is the 100% reference by definition, and the carrier is a single 110 Hz note.
One more practical difference: a vocoder needs a voice to feed it, sung or spoken in real time or from a recording, while a talk box needs only your mouth and a mic. A vocoder can run inside a DAW with no hardware at all. With a talk box, the mouthing has to happen live, in front of a microphone.
A short history of the talk box
The talk box is older than rock. Time magazine described Gilbert Wright’s Sonovox on 24 July 1939. Small transducers sat on the throat, where “These gadgets transmit the sound vibrations to the larynx”, and “The sound is shaped into speech by mouthing the desired words” (Time, 1939, reprinted by Jingle Samplers).
Vintage Guitar goes further and names a first talk box from the same year: “The first talk box was crafted by guitar maestro Alvino Rey in 1939”. In Rey’s setup his wife wore the throat mic: “she wore a carbon throat mic borrowed from military airmen”. The same article calls the Sonovox “the first true, commercial talk box” (Vintage Guitar, 2013).
From Nashville to The Bag
Steel guitarist Pete Drake’s version sent the sound through a tube straight into the mouth. “In 1964 Drake had an international hit on Smash Records” with “Forever”, played on his talking steel guitar (New Georgia Encyclopedia). The Country Music Hall of Fame describes his device as one that sent the steel’s sound “into his mouth via a plastic tube” (Country Music Hall of Fame).
Then the box went to market. “The Bag, built by Kustom Electronics in 1969, was the first mass-produced talk box,” according to Attack Magazine. It was a bag “running to a 30-watt driver housed in that sack”, where “The hose is held in the mouth, clamped between the teeth”, and it sold “all for a suggested retail price of $99.50” (Vintage Guitar, 2015). Vintage Guitar lists Steppenwolf, Jeff Beck on “She’s A Woman” from Blow By Blow and Stevie Wonder on Music Of My Mind among its users.
Bob Heil, Joe Walsh and Peter Frampton
Heil Sound credits Bob Heil with “the famed Talk Box for Joe Walsh and Peter Frampton” (Heil Sound). Heil didn’t invent the idea, but he made it loud enough for big rock stages. He told Vintage Guitar, “We grabbed a 250-watt JBL, built a low-pass filter”, and that “the first 50 were done in fiberglass”. “Heil sold rights to his Talk Box to Jim Dunlop in 1988”, the article adds. Dunlop’s HT-1 is that Heil Talk Box.
Frampton met the talk box through Drake. The Hall of Fame says he learned of it “during Harrison’s All Things Must Pass sessions”. Frampton remembers that Drake “got out this little box with a pipe, plugged in his steel and started playing.” Later Heil “started making talk boxes and gave me one as a present” (Premier Guitar, 2012).
NAMM’s oral history summary says “Bob Heil created a talk box that he gave to Peter as a Christmas gift in 1973”, and that Frampton later “established Framptone Products to sell his own line of talk boxes” (NAMM Oral History). I couldn’t confirm that year from a second primary source, so treat 1973 as NAMM’s date rather than a settled fact.
Richie Sambora’s part on Bon Jovi’s “Livin’ on a Prayer” is another famous example. MPR News explains that the guitar “is fed through a plastic tube into Sambora’s mouth” and is “picked up by a regular microphone” (MPR News, 2017).
Roger Troutman and the synth talk box
Roger Troutman of Zapp is the name most tied to the synth talk box. Attack Magazine writes that he played “Using an Electro Harmonix Golden Throat talk box paired with a Moog Minimoog”, and that later “Troutman made the switch to a Yamaha DX100”. Electro-Harmonix says he “made prominent use of his Golden Throat” on “California Love” (Electro-Harmonix).
Daft Punk are often named too, but the record is thin. In a 2001 interview quoted by Bjango, the duo said “every one of our vocal tracks uses a different vocoder effect”. Bjango’s analysis of their vocals finds no mention of a talk box from them, “despite Around The World almost certainly using one” (Bjango, 2025). That is an informed guess, not a confirmed fact, and I’d treat it as one.
Talk box hardware vs talk box plugins
Hardware is the only real talk box, because the filter is your mouth. A plugin can’t put a tube in your mouth, so it has to get the vowel shapes from somewhere else, almost always from a recorded or live voice. That makes a talk box plugin a close cousin of the vocoder.
The vendors say so in their own words. Antares describes Articulator as “a modern digital version of the classic talk box” whose job is to “Extract the formant and amplitude information from a vocal track” and apply it to another sound (Antares). iZotope’s Talkbox module in VocalSynth 2 advertises a “tube-free design and unique formant shifting feature”, and iZotope’s tip is to “Use Talkbox in sidechain mode with a monophonic carrier source” (iZotope, 2018). Back in 1998, Sound On Sound called the DigiTech Talker pedal a modern-day “incarnation of the talk box concept” and found “the talk box emulation is surprisingly authentic” (Sound On Sound, 1998).
So the choice is practical. A plugin is quiet, safe, works on any track in your VST host and can be edited after the fact. Hardware gives you the exact mouth shapes, the breath and the slurs between vowels that a voice-driven filter has to infer, and the performance is the sound. If you mostly want the effect in a mix, start with software. If you want to play it, you need the box.
Practical tips for using a talk box
- Respect the power rating. The HT-1 manual warns “Do Not use the Talkbox with a high wattage amplifier.” A passive box is fed from a speaker output, so the driver gets real amplifier power, not a line signal.
- Use the right cable. “Be sure to use a heavy duty speaker cable, not a standard guitar cable”, says the same manual. The manual also asks you to make sure your instrument amp and your mic amp are both grounded.
- Pick a rich, low patch. My test above shows why lower notes help: their harmonics sit closer together, so the mouth has more to shape. A sound needs harmonics in the first place, so a saw beats a sine. See my notes on the oscillator for starting waveforms.
- Exaggerate the mouth. Every consonant has to be made with lips and tongue alone, so over-articulate. Short words and simple vowels read best.
- Treat the mic as a vocal. High-pass the rumble, tame the sharp formant peaks with EQ, and keep the instrument’s dry sound low in the mix so the talking part leads. My entry on sound design has more on shaping sounds like this.
Frequently asked questions
What does a talk box do?
A talk box sends an instrument’s sound up a plastic tube into your mouth. You shape it with your mouth as if speaking, silently, and a vocal microphone picks it up. The result is a guitar or synth that seems to sing words. Dunlop’s Heil Talk Box HT-1 uses an 8 ohm driver rated at 50 watts RMS.
What is the difference between a vocoder and a talk box?
A talk box is acoustic: your real mouth filters the instrument. A vocoder is electronic: a bank of band-pass filters measures a voice and imposes those levels on the instrument. The Korg MS2000 uses 16 bands. In my model, 16 bands kept 44 to 53% of a vowel’s shape, depending on their range, which is one reason vocoders sound smoother.
Who invented the talk box?
No single person. Gilbert Wright’s Sonovox was described by Time in 1939, Alvino Rey built a guitar version the same year, Pete Drake had a hit with a tube device in 1964, and Kustom built The Bag in 1969. Bob Heil built the high-powered Talk Box for Joe Walsh and Peter Frampton.
Do you need an amp for a talk box?
For a passive box like Dunlop’s Heil HT-1, yes: it takes the speaker output of an amplifier, and Dunlop warns against high wattage amps. Boxes like the MXR M222 contain their own amp and run from an 18-volt supply. In both cases you also need a vocal microphone and a mixer or PA.
Can a plugin replace a real talk box?
Not exactly. A plugin has no mouth, so it takes formant and level information from a voice and applies it to another sound, which is how Antares describes Articulator. Its accuracy depends on how well it tracks formants. In my filter-bank vocoder model, even 64 bands kept only about 86% of a vowel’s shape compared with a mouth.
What talk box did Roger Troutman use?
Attack Magazine says Roger Troutman used an Electro-Harmonix Golden Throat with a Moog Minimoog, later switching to a Yamaha DX100 as the sound source. Electro-Harmonix says he made prominent use of his Golden Throat on California Love, which shows the classic setup: a synth into the box, then into a vocal microphone.
Sources
- Sound On Sound (Craig Anderton), www.soundonsound.com (2003-10)
- Dunlop Manufacturing (Heil Talk Box HT-1 manual), www.jimdunlop.com (undated)
- Jim Dunlop, www.jimdunlop.com (retrieved 2026-11-08)
- Jim Dunlop, www.jimdunlop.com (retrieved 2026-11-08)
- TheTalkStar, thetalkstar.com (retrieved 2026-11-08)
- Electro-Harmonix, www.ehx.com (2009-01-21, updated 2021-06-02)
- Attack Magazine (Adam Douglas), www.attackmagazine.com (2021-03-26)
- Vintage Guitar (Michael Dregni), vintageguitar.com (2013-09)
- Vintage Guitar (Michael Dregni), vintageguitar.com (2015-09)
- Time magazine, 24 July 1939 (reprint on Jingle Samplers), jinglesamplers.com (1939-07-24)
- New Georgia Encyclopedia, www.georgiaencyclopedia.org (n.d.)
- Country Music Hall of Fame, countrymusichalloffame.org (n.d.)
- Premier Guitar (Adam Perlmutter), www.premierguitar.com (2012-11-20)
- NAMM Oral History, www.namm.org (interview 2004-07-23)
- Heil Sound, heilsound.com (n.d.)
- MPR News, mprnews.org (2017-03-13)
- Bjango (Marc Edwards), personal analysis, bjango.com (2025-05-05)
- Sound On Sound, www.soundonsound.com (2000-05)
- Antares, antarestech.com (retrieved 2026-11-08)
- iZotope, www.izotope.com (2018-05-22)
- Sound On Sound (Paul White), www.soundonsound.com (1998-04)
- Princeton CS325 (after Peterson & Barney 1952, via P. R. Cook 1999), www.cs.princeton.edu (1999)
Back to Music Production Terms Index Page